Practical SQL JOIN Scenarios
Lesson 5.8 · Reading time: ~8 min · Practice tasks ↓
This lesson collects practical SQL JOIN scenarios: joining several tables along the relationships in the schema, aggregating joined data, finding missing data, and avoiding the two most common join mistakes: inflated totals and outer joins that lose their rows.
You know the join types; now the task is to apply them to real questions. Most report queries follow the same steps: find the tables that hold the data, connect them through their keys, filter, and aggregate.
Planning a Join Path
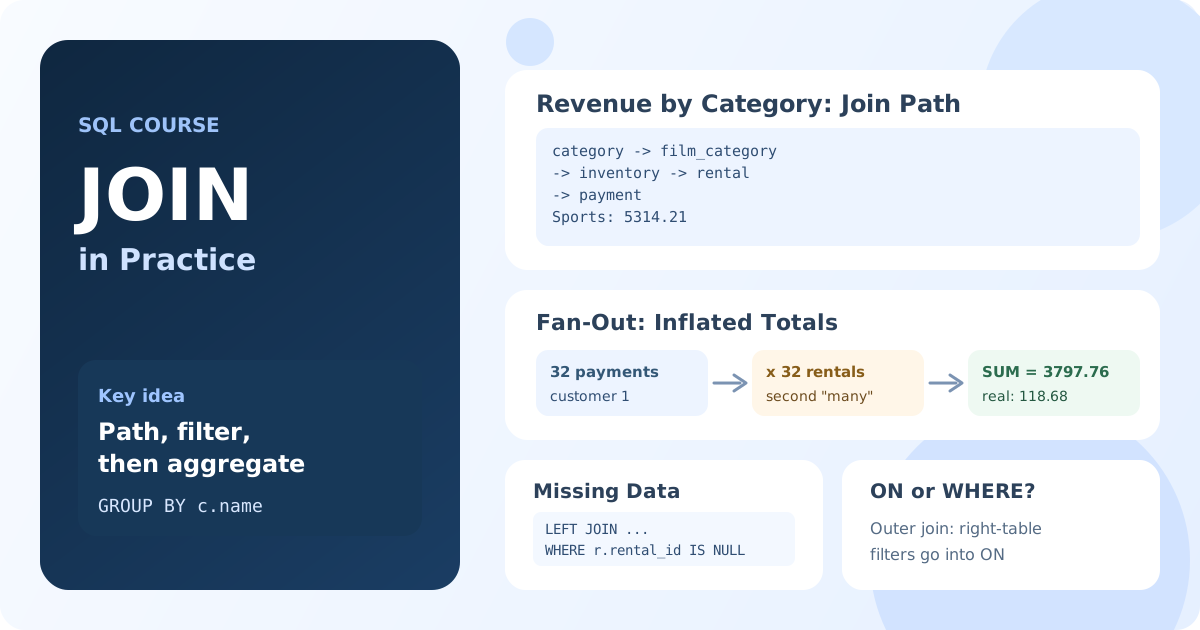
Start from the question and find a path between tables in the database diagram. "Revenue by film category" needs category, then film_category, film, inventory, rental and finally payment:
SELECT c.name AS category,
       COUNT(p.payment_id) AS payments,
       SUM(p.amount) AS revenue
FROM category AS c
INNER JOIN film_category AS fc ON fc.category_id = c.category_id
INNER JOIN inventory AS i ON i.film_id = fc.film_id
INNER JOIN rental AS r ON r.inventory_id = i.inventory_id
INNER JOIN payment AS p ON p.rental_id = r.rental_id
GROUP BY c.name
ORDER BY revenue DESC;
Result: 16 categories sorted by revenue; Sports and Sci-Fi are at the top.
The film table itself isn't needed: film_category and inventory both store film_id, so they can be joined directly. Join only the tables that hold data or are required to connect them.
Aggregating After a Join
Total spending of each customer:
SELECT c.customer_id,
       c.first_name,
       c.last_name,
       COUNT(*) AS payments,
       SUM(p.amount) AS total_spent
FROM customer AS c
INNER JOIN payment AS p ON p.customer_id = c.customer_id
GROUP BY c.customer_id, c.first_name, c.last_name
ORDER BY total_spent DESC
LIMIT 10;
Result: the 10 customers who spent the most.
Group by the key (customer_id), not only by the name: two different customers can have the same name.
The Fan-Out Trap: Inflated Totals
A join multiplies rows: a customer with 30 payments and 30 rentals becomes 900 rows if both tables are joined to the customer at once. Every sum over such a result is wrong.
-- Wrong: payments are multiplied by rentals
SELECT c.customer_id,
       SUM(p.amount) AS total_spent
FROM customer AS c
INNER JOIN payment AS p ON p.customer_id = c.customer_id
INNER JOIN rental AS r ON r.customer_id = c.customer_id
WHERE c.customer_id = 1
GROUP BY c.customer_id;
Result: 3,797.76 instead of the real 118.68: each of the customer's 32 payments was counted once for each of their 32 rentals.
Rule: don't join two independent "many" tables to the same row in one query. Here the rental table isn't needed at all. When you do need totals from two such tables, aggregate each one separately first; you'll learn how with subqueries and CTEs in Module 6.
Finding Missing Data
LEFT JOIN ... WHERE right_key IS NULL finds rows without a match. Customers who haven't rented anything since August 23, 2005:
SELECT c.customer_id, c.first_name, c.last_name
FROM customer AS c
LEFT JOIN rental AS r ON r.customer_id = c.customer_id
                     AND r.rental_date >= '2005-08-23'
WHERE r.rental_id IS NULL
ORDER BY c.customer_id;
Result: customers without rentals in the last days of the data.
Note the date condition: it is in ON, because it limits which rentals count as a match. In WHERE it would remove all unmatched customers, and the query would return nothing.
WHERE vs ON in Outer Joins
The previous example shows the general rule for LEFT JOIN:
| Condition on | Put it in | Effect |
|---|---|---|
| the right table, to limit matches | ON | Left rows stay; only matches are filtered |
| the left table | WHERE | Left rows are removed from the result |
the right table's key IS NULL | WHERE | Keeps only rows without a match (anti-join) |
For INNER JOIN, ON and WHERE give the same result, so the placement is a matter of readability.
Key Takeaways:
- Plan the join path through the schema and join only the tables you need.
- Group by keys, not only by names.
- Joining two "many" tables to the same row multiplies rows and inflates sums and counts.
LEFT JOIN ... WHERE key IS NULLfinds missing data.- In outer joins, conditions on the right table belong in
ON.
Frequently Asked Questions
How do I join more than two tables in SQL?
Add one JOIN ... ON ... for each table, following the foreign keys in the schema. Each join connects a new table to the tables that are already in the query.
Why does my SUM return a much larger number after a JOIN?
Because the join multiplied the rows: each row of one table was repeated for every matching row of another. Remove tables you don't need, or aggregate each table separately before joining the results.
Should a filter go in ON or in WHERE?
For INNER JOIN it doesn't matter. For LEFT JOIN, a condition on the right table goes in ON; in WHERE it removes the unmatched rows and turns the outer join into an inner one.