SQL Correlated Subqueries
Lesson 6.3 · Reading time: ~6 min · Practice tasks ↓
A SQL correlated subquery is a subquery that refers to a column of the outer query, so its result depends on the current outer row. In this lesson you'll learn how a correlated subquery is evaluated, how to compare a row with its own group, how to use correlated subqueries in SELECT and with EXISTS, and when a JOIN is the better choice.
The subqueries in the previous lessons were independent: you could select the inner query and run it on its own. A correlated subquery can't run alone, because it uses a value from the row the outer query is currently looking at. This lets you ask questions relative to each row: "is this film more expensive than the average of its rating?", "what is the longest film in this category?".
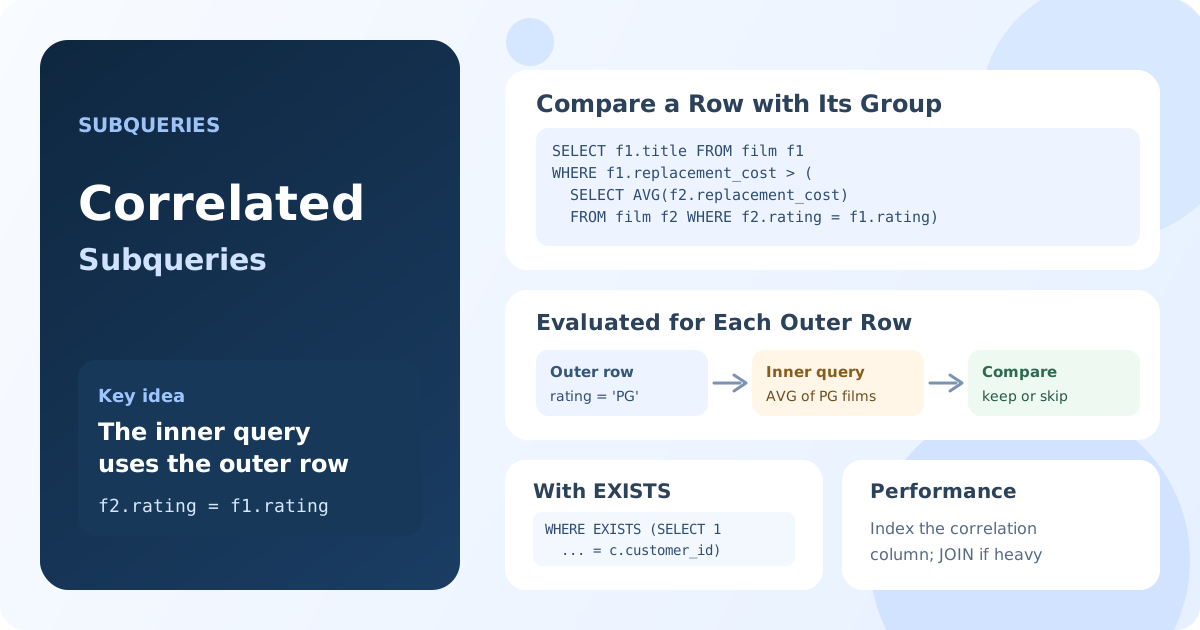
How a Correlated Subquery Works
Logically, the database evaluates a correlated subquery like this:
- Take a row of the outer query.
- Run the inner query, substituting values from that row.
- Use the result to evaluate the condition or the column for the row.
- Move to the next row and repeat.
The link between the queries is a condition in the inner query that uses an outer alias, for example f2.rating = f1.rating. Aliases are essential: without them, it is unclear which copy of a table a column belongs to.
Comparing a Row with Its Group
Films whose replacement cost is higher than the average for their rating:
SELECT f1.title, f1.rating, f1.replacement_cost
FROM film AS f1
WHERE f1.replacement_cost > (
    SELECT AVG(f2.replacement_cost)
    FROM film AS f2
    WHERE f2.rating = f1.rating
)
ORDER BY f1.rating, f1.replacement_cost DESC;
Result: films that cost more to replace than the average film of the same rating.
For a film rated PG, the inner query calculates the average of PG films; for an R film, the average of R films. A non-correlated subquery could only compare with one overall average.
Correlated Subqueries in SELECT
A correlated subquery in the SELECT list returns one value for each row. The number of films in each category:
SELECT c.name AS category,
       (SELECT COUNT(*)
        FROM film_category AS fc
        WHERE fc.category_id = c.category_id) AS films
FROM category AS c
ORDER BY films DESC;
Result: 16 categories with their film counts, from Sports (74 films) down.
It can also return a value that is hard to get with GROUP BY, such as the title of the longest film in each category:
SELECT c.name AS category,
       (SELECT f.title
        FROM film AS f
        INNER JOIN film_category AS fc ON fc.film_id = f.film_id
        WHERE fc.category_id = c.category_id
        ORDER BY f.length DESC, f.title
        LIMIT 1) AS longest_film
FROM category AS c
ORDER BY c.name;
Result: each category with the title of its longest film; ties are resolved by title.
A subquery in SELECT must return one row and one column; otherwise the query fails.
Correlated Subqueries with EXISTS
EXISTS checks whether the inner query returns at least one row, and it is almost always correlated. Customers who have rented at least one copy from store 2:
SELECT c.customer_id, c.first_name, c.last_name
FROM customer AS c
WHERE EXISTS (
    SELECT 1
    FROM rental AS r
    INNER JOIN inventory AS i ON i.inventory_id = r.inventory_id
    WHERE r.customer_id = c.customer_id
      AND i.store_id = 2
)
ORDER BY c.customer_id;
Result: customers with at least one rental of a store 2 copy. SELECT 1 is a convention: EXISTS only checks whether a row exists, not what it contains.
NOT EXISTS finds rows without a match, like the LEFT JOIN ... IS NULL anti-join from Lesson 5.3.
Performance
The "run for each row" description is the logical model. Modern optimizers often rewrite correlated subqueries into joins or semi-joins, especially EXISTS and IN. Still:
- A correlated subquery in
SELECTor in a complexWHEREcan really run once per outer row and become slow on large tables. - An index on the correlation column (here
film_category.category_id,rental.customer_id) makes each inner run fast. - If one inner result is needed for many columns, a
JOINwith a grouped subquery or a CTE (Lesson 6.4) is usually clearer and faster.
Check the plan with EXPLAIN when a query with a correlated subquery is slow.
Key Takeaways:
- A correlated subquery refers to a column of the outer query and can't run on its own.
- Logically, it is evaluated once for each outer row.
- It is the natural tool for comparing a row with its own group.
- In
SELECT, it must return exactly one value. EXISTSandNOT EXISTSare typical correlated subqueries.- Index the correlation column; consider a
JOINor CTE for heavy queries.
Frequently Asked Questions
What is the difference between a correlated and a non-correlated subquery?
A non-correlated subquery is independent: it runs once, and its result is used for all rows. A correlated subquery uses values from the outer row, so its result can be different for every row.
Are correlated subqueries slow?
They can be, because logically they run for every outer row. In practice, optimizers often convert them to joins, and an index on the correlation column helps a lot. Check the execution plan with EXPLAIN.
Can a correlated subquery be replaced with a JOIN?
Usually yes. For example, comparison with the group average can be written as a join with a grouped subquery: JOIN (SELECT rating, AVG(replacement_cost) AS avg_cost FROM film GROUP BY rating) AS r ON r.rating = f.rating.